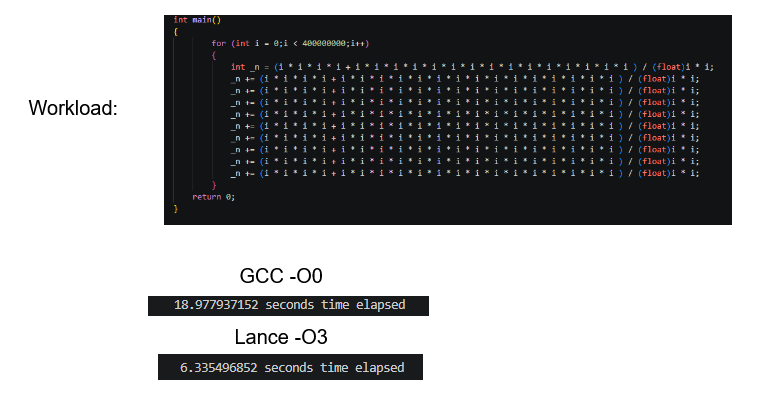
I added AVX2 for-loop auto-vectorization to my C compiler, Lance
Here is GCC -O0 vs Lance -O3 (new optimization flag! enables autovec)
At first it was SSE1-4 autovectorization, but that turned out to not provide gains at all. AVX2 is far less disappointing!
Function calls can also be auto vectorized, through function inlining. Non-inlined function calls will prevent auto-vectorization
And of course with AVX2 comes AVX2 instruction encodings, which have been added to my custom instruction encoder as well