I added more optimizations to my C compiler, Lance
Specifically, CSE and while-loop autovectorization.
When CSE is enabled, the compiler generates much more efficient code, reusing previously computed expression results.
The compiler also self-hosts well even with these new optimizations enabled, with SHA-256 hashes matching between each self-build generation's object files.
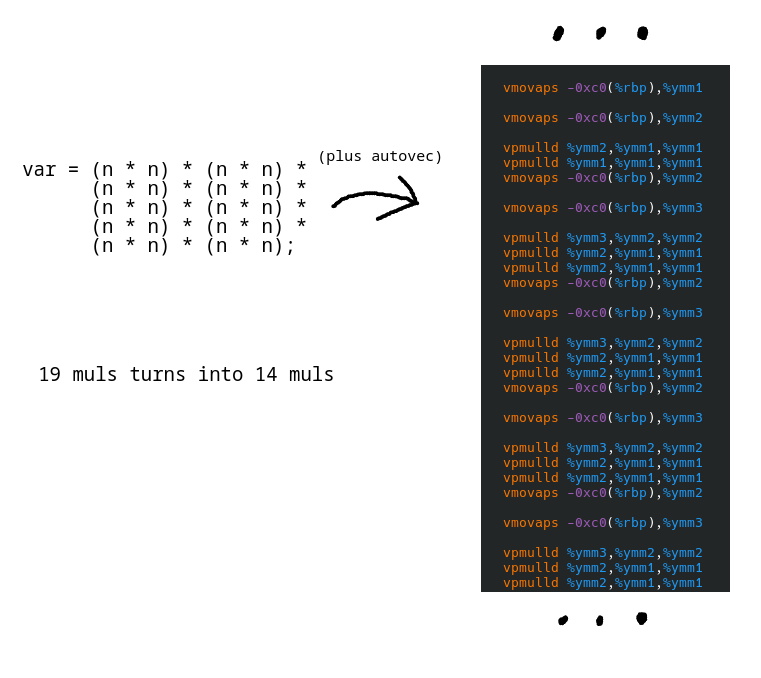
Here is a demonstration of this new optimization in action. (I don't show while-loop autovec here because it would take too much space in the image!)