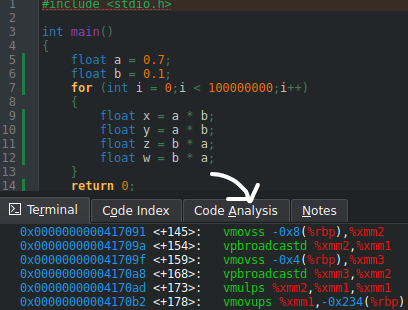
My C compiler, Lance, had MASSIVE overhead with SLP vectorization.
It's mostly eliminated now.
Here it shows how that entire loop body (without using loop autovec) can be compiled into 6 instructions with the optimized SLP vectorizer. The old one would compile it to about 22 instructions.
And yes, it beats GCC's -O0 by 30-40% on this example. This example code is very simple for demonstration purposes and on more complicated code (especially on integer code), it can be 0.5-4x as fast (proper cost model WIP)